Multi-Engine Translation Routing: Why No Single AI Model Wins Every Language Pair
Multi-engine translation routing sounds obvious and is harder than it looks: how to decide which engine handles which language pair, and when not to bother.
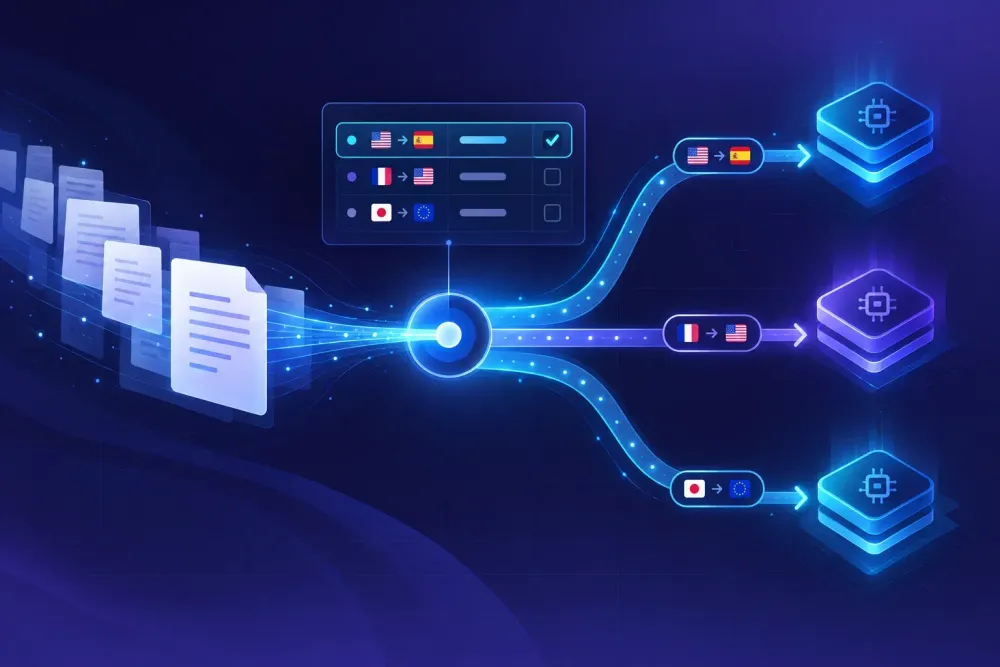
Most agencies we talk to picked an engine once and then stopped thinking about it. That is defensible, and for plenty of workloads it is the right call. But once you are running more than three or four language pairs, multi-engine translation routing deserves a serious look, because the single-engine setup rests on an assumption that does not survive contact with real files: that one system is best at everything. Quality gaps between engines are not flat. They cluster by language pair, by content type, and by how much context you can hand the engine before it starts working. Routing means matching each job to the engine that handles it best, instead of sending everything to one and paying for the difference in post-editing.
What multi-engine translation routing actually means
Routing is a decision layer, not a product you buy. Somewhere between the incoming file and the translated output, something chooses which engine handles this particular job. That something can be a project manager with a spreadsheet, a rule inside your automation, or a quality-estimation score consulted at runtime.
Most teams already do a rough version of this without naming it. A PM who sends EN>JA through one tool and EN>DE through another is routing. So is the translator who has quietly decided that one engine gets the contracts and another gets the marketing decks. The difference between that and a routing policy is whether the decision is written down, tested and reviewed, or whether it lives in one person's head and leaves the company when they do.
Two neighbouring ideas are worth separating out. MT engine routing is not ensembling, where several engines translate the same segment and something merges or picks among the outputs. Ensembling is heavier, more expensive, and mostly the province of teams with their own evaluation infrastructure. Routing is also not the same as switching engines mid-project, which is one of the more reliable ways to introduce terminology drift into a file that was previously consistent.
Routing at the level we are describing is deliberately coarse. One engine per pair, or per pair and content type, decided before the project starts and held for its duration. The coarseness is a feature rather than a limitation. It keeps the decision auditable, it keeps handover notes short, and it keeps the TM clean, because everything in a given client program and language pair came from the same place and reads the same way. A routing policy you can explain to a new project manager in four sentences will survive. One that requires a flowchart will not.
Why no single engine wins every language pair
The underlying reason is unglamorous: training data is distributed unevenly, and the architectures behind the engines you can actually buy were optimised for different things.
Dedicated NMT systems were built for one job, turning a source segment into a fluent target segment. On high-resource European pairs with abundant parallel data they are very good at exactly that, and they are fast and cheap while doing it. LLM-based translation is doing something else. It reads more context, follows written instructions about register and terminology, and can be told what kind of document it is inside. On pairs where parallel data thins out, or where the right answer depends on knowing that this paragraph is a warranty clause rather than marketing copy, that context tends to matter more than raw sentence-level fluency.
Then there is distance and morphology. Pairs that need restructuring rather than substitution, and pairs where the target language must encode information the source left implicit, punish engines in different ways. Japanese and Korean force decisions about politeness level that English never marks. Slavic pairs force case agreement across clauses that a segment-level system cannot always see. We have written before about which language pairs AI translates well in 2026 and which still need a human, and the shape of that list has been fairly stable even while the engine rankings inside it have not.
House style is the third axis and the one teams consistently underweight. An engine that produces technically accurate German your reviewer rewrites every time is more expensive than a slightly less accurate one that lands closer to the client's voice. Accuracy scores do not see that gap. Your post-editing hours do.
None of this means you need four engines. It means the belief that one engine is uniformly best is an assumption rather than a finding, and it happens to be cheap to test.
Two routing decisions that paid off, and one that did not
Consider a mid-sized agency running six pairs. Their German technical work, mostly datasheets and installation manuals arriving as DOCX import, went through an NMT engine with a locked glossary. Their French and Spanish marketing work went through an LLM with a two-paragraph style brief and explicit permission to restructure sentences. Before the split, everything went through the LLM, and the German post-editors kept filing the same complaint: fluent output that quietly paraphrased terms the glossary had pinned. After the split, the German files needed fewer terminology corrections per thousand words, and the French files read better without a reviewer rewriting the first sentence of every paragraph. Neither improvement was dramatic alone. Together they moved close to a working day a month out of post-editing.
The second case was driven by format rather than language. A client's product catalogue arrived as an XLSX workbook: thousands of cells of two to five words each. Cell-level XLSX workbook translation is a context-starved problem. "Cover" could be a noun or a verb, and no engine can tell from the cell alone. What worked was routing all short-cell work to the engine that accepted a column of surrounding context plus a category hint, regardless of which pair it was going into. The shape of the source mattered more than the language.
The one that did not work is more instructive. A twelve-pair software documentation program was split across three engines by pair. Each engine performed well on its own files, and every QA report came back clean. The problem surfaced at the client, who read four of the twelve languages and noticed that the same feature name had been handled three different ways. The glossary covered product nouns. It did not cover tone, and tone is exactly where three engines disagreed visibly. They consolidated back to two engines and accepted a slightly worse score on one pair in exchange for a program that sounded like one company.
How to build a routing table without guessing
The method is boring and it works. Pull 300 to 500 segments per pair out of real delivered projects, ones where you already have an approved target. Not benchmark sentences. Your files, your clients, your terminology, including the awkward parts you would not put in a portfolio.
Run each candidate engine over that set with identical inputs: same glossary, same instructions, same segmentation. This is the step teams skip, and skipping it means you are measuring your prompt rather than the engine. If one engine receives a glossary and another does not, the comparison tells you nothing you can act on.
Then score twice. A learned metric such as COMET gives you a cheap first pass and is fine for ranking candidates, and we have found it directionally reliable for spotting a clear loser. After that, have a reviewer actually post-edit a subset and record minutes per thousand words. That second number is the one that pays your bills. An engine can score lower and still be cheaper to work with, because its errors are the kind a reviewer fixes in two seconds, and error type is largely invisible to automatic scoring.
Write the result into a table: pair, content type, chosen engine, date tested, post-editing minutes per thousand words. Six rows is already a real routing policy. Re-run it quarterly, because engine versions move underneath you without announcements, and a routing decision from eighteen months ago is a guess wearing a table's clothing.
If you are still at the stage of choosing which candidates to test, our comparison of DeepL API, OpenAI API and Google Translate for agency workflows covers the practical tradeoffs before you start measuring anything.
Route on content type, not only on language pair
Once teams have a routing table in front of them, the more useful axis usually turns out to be what the document is rather than which language it is going into.
Contracts and regulatory text reward literalism and punish creative rewriting. An engine that improves on the source's phrasing is doing damage, and the reviewer has to undo it clause by clause. Marketing copy is the inverse case: the client wants something that reads as if it had been written in the target language, and an engine that tracks source word order produces text a reviewer rewrites from scratch anyway. Sending both through the same engine means one of them is being handled by the wrong tool.
PPTX presentation translation adds a constraint neither of those has, which is length. A German target thirty per cent longer than its English source breaks a 40-character text box, and no amount of terminology accuracy rescues a slide where the heading has wrapped to four lines and pushed the body text off the bottom. Engines differ in how well they respect an explicit length instruction. That difference is easy to test and almost never tested.
Short-string content is its own category. UI strings, table headers, spreadsheet cells, navigation labels. Context is thin, ambiguity is high, and the useful question becomes which engine does the least damage when it has almost nothing to work from. Some guess confidently and wrongly. Others hedge toward the most common reading, which is usually what you want when a reviewer is going to check every string regardless.
In practice this means your table probably needs more rows on the content-type axis than on the language axis. A four-pair shop with three content types has twelve cells, and most will resolve to the same engine. The handful that do not are where routing earns its complexity.
What routing costs you, and when a single engine is better
Every engine you add is another glossary format to maintain, another set of instructions to keep current, another vendor in your security review, another invoice to reconcile, and another set of QA baselines your reviewers have to hold in their heads. None of that appears in a quality comparison, and all of it lands on the same two or three people.
Terminology drift is the real risk. A glossary transfers between engines cleanly enough. Tone does not. If two engines handle the same client's content in different languages, and that client reads both, expect a question about why the brand sounds different in French. The mitigation is to route by pair within a program rather than splitting one pair's content across engines, and to keep a single glossary as the source of truth that every engine receives unchanged.
TM hygiene is the second cost. If you feed approved output back into a translation memory, mixed-engine content makes that TM less internally consistent, which returns later as fuzzy matches that need more editing than their match percentage promised. The damage is slow and easy to misattribute.
Routing works best when you have five or six active pairs, enough volume per pair to measure anything at all, and someone whose job includes looking at the numbers once a quarter. It does not apply if you run two pairs, or if your monthly volume is a handful of files, or if nobody owns the measurement. Below that threshold the right answer is one engine, one well-maintained glossary, and the saved effort spent on prompt and glossary quality instead. We have watched more than one team get a bigger improvement from tightening a glossary than any engine swap would have produced, and at a fraction of the operational overhead.
Where to start
Take your two highest-volume pairs and one content type you deliver often. Build the 300-segment test set from files you have already delivered and had approved. Run your current engine and one alternative across it with identical glossary and instructions, then have a reviewer post-edit forty segments from each and record the minutes. If the gap in post-editing time comes in under roughly ten per cent, stay where you are and put the effort into your glossary. If it is over twenty per cent, you have found the first row of your routing table.
Then write the table down, date it, and set a quarterly reminder against it. The teams getting value out of multi-engine translation routing are not the ones running the most engines. They are the ones who can say why each pair goes where, and when they last checked that it was still true.