How to run a bilingual review without a CAT tool
How to run a bilingual review without a CAT tool: the spreadsheet columns, the checks that catch real errors, and how to merge reviewer edits back.
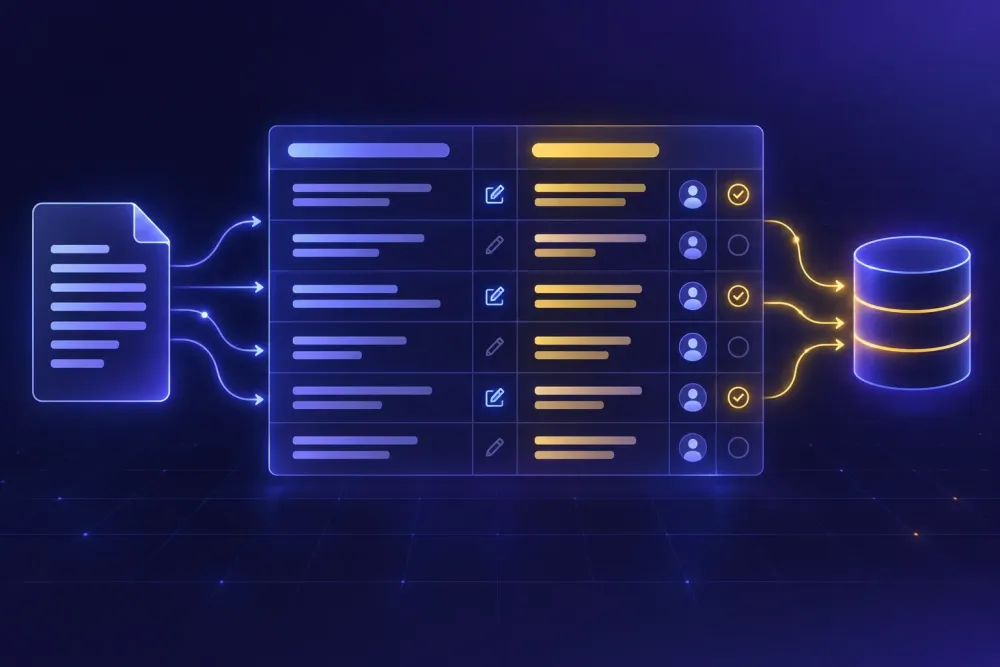
Running a bilingual review without a CAT tool sounds like a downgrade, and sometimes it is. But most review passes we see do not need a CAT editor at all. They need the source and the target sitting next to each other, a stable way to point at one specific segment, and somewhere for the reviewer to record what they changed. A spreadsheet does all of that. We have watched agencies burn two weeks trying to get a client's engineer into a CAT seat when that engineer would have returned a two-column sheet in three days.
Below is the setup we use when the review has to happen outside a CAT tool, along with the point at which it stops being good enough.
What a bilingual review actually needs
Strip a review pass down and there are four requirements.
The reviewer has to see source and target together, at segment level, in the order the reader will meet them. They need to know where each segment lives in the original file, because "the sentence about torque limits" is useless feedback and "row 412, page 38, table 7" is not. They need somewhere to write the corrected text without destroying the original translation, so you can still tell what changed. And whoever owns delivery needs those decisions in a form that can go back into the file and into the TM.
Nothing on that list requires a CAT tool. What a CAT tool adds on top is TM and fuzzy-match context during review, inline QA rules, concordance search, segment locking, and status tracking per segment. Those matter during translation. During review they are conveniences, and a few of them get in the way: a subject-matter expert who has never opened a CAT editor will spend the first hour fighting the interface instead of reading the text.
The cost is real on the other side too. CAT seats cost money, client-side reviewers rarely want an account, and the onboarding call eats the schedule. We have had client reviewers refuse outright. An external reviewer who will not log in is not a quality problem, it is a logistics problem, and logistics problems have cheaper fixes.
So the honest question is not whether a spreadsheet matches a CAT editor. It is whether the review you are trying to run actually depends on the things only a CAT editor gives you. For a final accuracy and terminology pass on content that is already translated, usually it does not.
How to run a bilingual review without a CAT tool
The shape of the workflow is the same whether the translation came from a human, from MTPE, or from an AI step.
Export the content as a source/target table, one row per segment. Most tools will produce a bilingual export of some kind. If you worked outside a CAT tool entirely, build that table at the point of translation rather than aligning two finished files afterwards, because alignment is where this goes wrong.
Add the review columns before you send the sheet, not after. A reviewer who has to invent a commenting convention will invent a different one than the next reviewer did.
Send it with a one-paragraph brief. Say what you want checked and what you do not. "Terminology and factual accuracy, please do not restyle" saves more time than any tooling decision on this list. Without it, half of what comes back is preference.
Merge the edits by segment ID, update the glossary in the same session, then push the approved target column into the TM.
Two details decide whether this is pleasant or awful. The first is segment IDs that survive the round trip. If your IDs are row numbers and the reviewer sorts or inserts a row, the mapping is gone, which is why the ID column should hold values and never formulas. The second is the brief. We keep coming back to it because it is the step people skip.
Building the sheet so reviewers work fast
A review sheet we would actually send has eight columns: ID as plain text, location, source, target as delivered, reviewer edit, issue type, severity, comment. Location is something like "ch4 / p38 / table 7 / cell B2" or "slide 22 / body".
Keeping the edit in its own column instead of overwriting the target is the thing most people get wrong, and it costs them later. With a separate column you can count how many segments were touched, diff old against new, work out an edit rate, and defend the translation when a client claims the whole file was unusable. With overwriting you have a new file and no argument.
Then make the sheet physically comfortable. Freeze the header row and the ID and location columns. Turn on wrap text and set source and target to roughly the same width so the eye can compare lines. Row height to auto. Lock everything except the three reviewer columns, which takes a minute in Excel or Google Sheets and prevents the most common accident, a reviewer typing over source text.
Use dropdowns for issue type and severity rather than free text. Our list is terminology, accuracy, omission, number or date, formatting, and style, with severity as critical, major, or minor. The taxonomy matters less than being able to filter and count what comes back.
Add conditional formatting so any row with a non-empty reviewer edit changes colour. Reviewers like watching their own progress, and when the sheet comes back you can read the shape of the review in three seconds.
Checks you can run inside the sheet
A spreadsheet is bad at linguistic QA and good at arithmetic, so use it for the mechanical errors reviewers miss while concentrating on meaning.
Digit comparison catches the error class with the worst consequences. In Google Sheets, =REGEXREPLACE(C2,"[^0-9]","") against the same formula on the target column flags any segment where a figure changed. Recent Excel 365 builds have REGEXREPLACE too. We have caught a transposed invoice amount and a wrong model number this way, both in documents two humans had already read.
Length delta, =LEN(D2)-LEN(C2), is a rough signal. On ordinary prose it means little. On table cells, chart labels, and slide text boxes it tells you which segments are about to overflow the space they have.
Untranslated segments show up with =EXACT(C2,D2), which is worth running because a copied source segment reads as fluent and gets skipped.
For consistency, build a pivot table on the source column and count distinct targets. Identical source segments with different translations are either a real contextual difference or a mistake, and someone should look either way. This is the same logic behind a pre-delivery QA check, just done in the only tool the reviewer has open.
Two reviews that went this way
A three-person agency we work with had a 180-page DE to EN supplier manual. The client's in-house engineer was the only person who knew the part names, and he was never getting a CAT seat. They sent him a source/target sheet with chapter and page in the location column.
He came back in four days with 94 edited segments out of roughly 2,840. Almost all of them were two part names translated inconsistently, and those went straight into the glossary. The edit count was the useful output: it told the PM that a glossary fix plus a targeted search and replace would do, instead of the full re-read she had budgeted.
The second was a freelancer with a 60-slide sales deck, EN to ES. The reviewer was the client's regional manager. Bilingual, no CAT experience, no patience. The sheet carried slide numbers, and that one detail changed what came back. Three segments got the note "will not fit the box", which no QA rule would have caught, because nobody had declared a character limit anywhere. The manager could picture the slide. A list of segments with no slide reference would not have produced that feedback.
Neither review needed TM lookup. Both needed the reviewer to actually start.
We have seen it fail, too. A set of contracts with heavy inline formatting came back from spreadsheet review with the bold and italic runs gone, because the flattened text gave no sign they had ever been there. That brings us to the limits.
Where spreadsheet review falls short
Inline formatting and tags are the hard limit. A spreadsheet cell holds text, so bold inside a sentence, footnote markers, cross-references, and placeholders either disappear or have to be rendered as visible markers that reviewers then edit by accident. Content that is mostly plain prose survives this fine. Heavily tagged content does not, and that is where a CAT editor earns its seat price.
Reading order is the second problem. Segment order in an export follows document structure, not the path a human eye takes across the page. Multi-column layouts, tables meant to be read across rather than down, and footnotes all shuffle in ways that make some passages hard to judge in isolation. Sending the rendered source file alongside the sheet fixes most of that.
There is no concurrency control worth the name. Two reviewers in one cloud sheet will overwrite each other unless you split by row range and say so explicitly. Local copies are worse, because then you are merging two versions of the sheet by hand.
Reviewers also lose the reasoning behind the text. In a CAT tool they can see that a segment came from a 95% TM match and leave it alone. In a sheet every segment looks equally new, which pushes some reviewers toward over-editing. The brief helps with that, though it does not fix it.
And the edits do not reach the deliverable on their own. Someone applies them, and that step is where fresh errors enter. If your pipeline can re-import an edited bilingual sheet, use it. If not, put the manual application time in the schedule instead of treating it as a rounding error.
None of this applies evenly. For a long-running account with a mature TM, a deadline measured in hours, or heavily structured content, review inside the CAT tool is the right call. For a one-off document, an external expert, or a client who wants to check their own terminology, the sheet wins, because it is the version they will actually open.
Getting edits back into the deliverable and the TM
Merge on ID, never on text. Sort the returned sheet by ID, confirm the row count matches what you sent, and only then touch the file. A count that has changed means someone inserted or deleted a row, and you want to know that before you start applying edits rather than halfway through.
When you have to apply edits by hand, work from the longest segments to the shortest. Short strings collide with substrings of longer ones, and a search and replace in a 180-page DOCX will happily make the same wrong change in forty places.
Then do three things while the context is still in your head. Put the terminology decisions in the glossary, because a reviewer correcting the same term twice is telling you the glossary was wrong, not that the translator was careless. Push the approved target column into the TM, which most tools will take as TMX or as a bilingual Excel import. And record the edit rate, segments touched divided by total segments, somewhere you will see it next time. That number is the cheapest quality signal available, and it often says more about an engine or a vendor than a quality score does, because it reflects what a reviewer thought was worth changing.
This is also the moment to decide what the next project looks like. If the edits cluster in one content type, that content type needs a different preparation step, not a stricter review.
If you want the AI translation step itself to produce this kind of reviewable artifact, that is roughly what we built SnapIntel for. You create a project from a DOCX, XLSX, or PPTX file, approve the glossary and the translation prompt before the job starts, and the completed job returns the translated file plus a neutral source/target XLSX export and a QA report. That neutral export is a bilingual sheet you can send to a reviewer or load into any CAT tool, which is why we treat it as a deliverable rather than a debug artifact.
The setup, as a checklist
Build it once and reuse it.
Make a template sheet with the eight columns, dropdowns for issue type and severity, frozen panes, protected source and target columns, and the three formulas already sitting in helper columns. Save it where your PMs can find it without asking.
Write the brief template too. One paragraph: what to check, what to leave alone, which columns to fill, the deadline, who to ask. Half a page of instructions gets ignored, so keep it short enough that nobody skips it.
Before you send, confirm three things: IDs are values, the location column is filled, and you have noted the row count. When it comes back, check the row count, merge longest to shortest, update the glossary, update the TM, and record the edit rate.
Post-editing has become a standard service line rather than an exception, a shift both Slator and Nimdzi have tracked in their industry reporting. Which means the review pass, not the translation pass, is where most of the human time in a project now sits. On both projects above, the thing that moved the schedule was not the tooling. It was that the reviewer opened the file the day it arrived.